Ancient-DNA Genomic Report
Sequencing analysis of degraded coffee-bean DNA samples against the Coffea arabica reference genome.
Last updated: September 21, 2026
About this report
This report summarizes the bioinformatics pipeline results for each sample: variant calls, per-contig coverage, and local read depth around called SNPs. Select a sample below to view its full breakdown.
Fresh brew of results ☕
Ancient DNA recovered from the Vrouw Maria wreck, sequenced and called against the reference genome.
Preliminary results — the pipeline is still being refined and these results may change.
Last updated: September 21, 2026 — all 4 samples rerun with fastp adapter/quality trimming (see each sample's Sample Quality Control card for the pre/post comparison).
Authentic Ancient-DNA Damage Signature
Direct molecular evidence the recovered coffee DNA is genuinely of historical origin — independent of how little of it survived. See the full write-up for the per-sample numbers and the 5′/3′ asymmetry explanation.
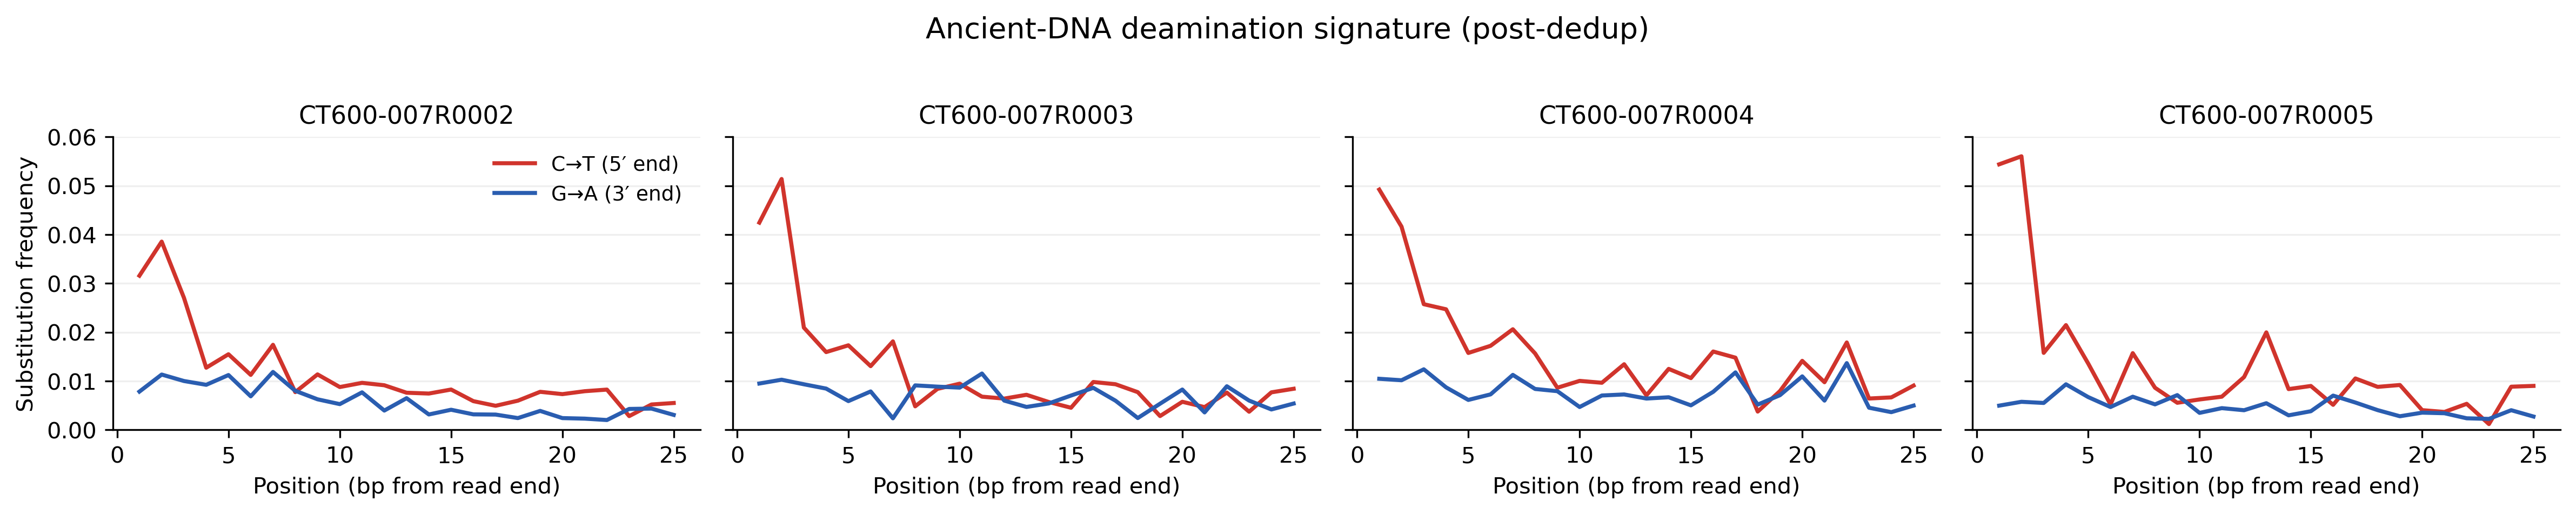
All 4 samples show the classic aDNA deamination signature: elevated 5′ C→T substitution frequency right at the read terminus (red), decaying to baseline within ~8–10bp. That decaying spike is specific to genuinely ancient, degraded DNA — modern contaminant DNA doesn't show it.
Metagenomic Screening
Taxonomic classification of sequencing reads against the NCBI reference database, run on the same Vrouw Maria samples. See the Metagenomic Screening guide for why this exists and how it works.
Preliminary — screened for R0003/R0004 so far; R0002/R0005 pending.
Last updated: September 19, 2026
Documentation
About the Researcher
Vrouw Maria
Shipwreck · Parainen, Finland
[A one-line hook — what the Vrouw Maria is, and why she matters to this project.]
[Placeholder: the history of the wreck, its discovery, and its role as the archaeological source of the coffee-bean samples analyzed in this study.]